

TL;DR
This post is for architects who want to add tracing to Aiven for OpenSearch® and need to know what it takes to run the pipeline.
Aiven for OpenSearch includes Trace Analytics in OpenSearch Dashboards, so you can follow a request across services, see which services call which, and open the logs a slow span wrote. OpenTelemetry collects the traces, and Data Prepper writes them to the span and service map indexes that Trace Analytics reads. Add Aiven for Apache Kafka® as a buffer when you need to absorb bursts of spans during an incident or replay them after a pipeline change.
When an alert says checkout latency has doubled, the logs tell you which service is reporting errors but not where the time went. A single request can pass through a gateway, several services, a queue and a database before it returns, and each of them writes its own logs. Distributed tracing connects those steps. Every request gets a trace ID, every unit of work inside it becomes a span with a start time, a duration and a parent, and together the spans form a timeline of one request across every service it touched.
In the first post, Observability is a data problem, we described traces as structured events with timing attached. The previous post, Centralizing logs: Apache Kafka® + OpenSearch®, covered getting logs into Aiven for OpenSearch. This post adds traces to the same cluster, using OpenTelemetry for collection, Data Prepper for processing and Trace Analytics for investigation.
Routing traces from OpenTelemetry to OpenSearch
A trace pipeline on OpenSearch has four stages, and only the last two are specific to OpenSearch.
- Instrument. OpenTelemetry SDKs, or zero-code instrumentation for languages such as Java, Python and Node.js, create spans inside your applications and export them over the OpenTelemetry Protocol (OTLP).
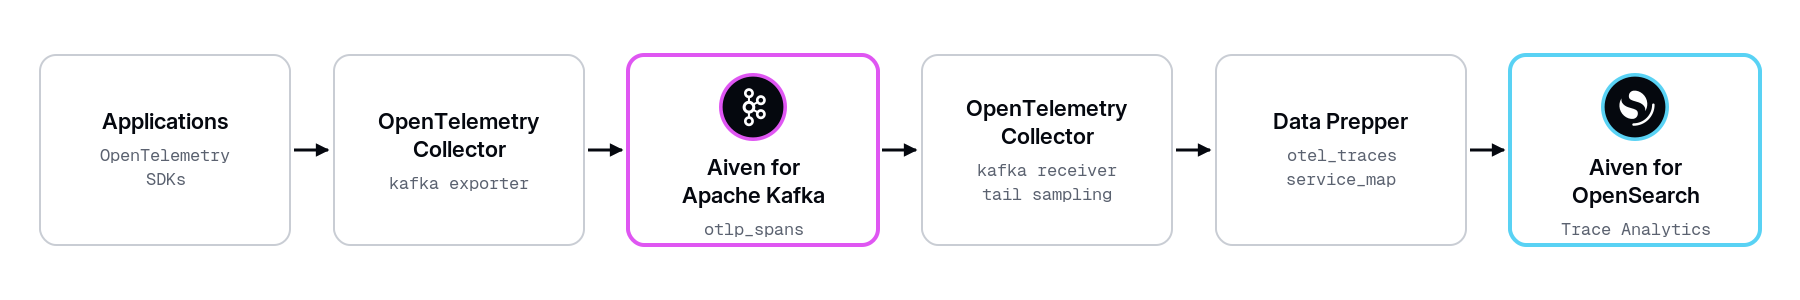
- Collect. The OpenTelemetry Collector receives spans from many applications, batches them, applies sampling and forwards them. Applications know only the collector's address, so you can change everything after it without redeploying them, the same principle as the log forwarders in the previous post. Other pipeline tools that send OTLP, such as Vector, can replace or supplement the collector, because Data Prepper accepts standard OTLP.
- Process. Data Prepper, the OpenSearch project's ingestion tool, receives OTLP from the collector and prepares spans for search. Its
otel_tracesprocessor copies trace-level fields, such as the root span name and the duration of the whole trace, onto every span. Itsservice_mapprocessor works out which services call which. - Search. Data Prepper writes spans to the
otel-v1-apm-spanindex and service relationships to theotel-v1-apm-service-mapindex in Aiven for OpenSearch, and Trace Analytics in OpenSearch Dashboards reads both.
OpenTelemetry is a Cloud Native Computing Foundation project, and like Data Prepper and OpenSearch it is open source under the Apache 2.0 license, so every piece of this pipeline is open source. The instrumentation in your code also stays the same whichever backend stores the spans, and you decide where traces go in the collector configuration, which matters later in this post when Kafka enters the picture.
Ingesting traces into OpenSearch
In this setup, you run Data Prepper in your own environment, as a container or on a virtual machine next to your collectors, and it connects to Aiven for OpenSearch like any other client. Aiven for OpenSearch accepts HTTPS connections only and always requires user authentication, so the OpenSearch sink needs the service URI and a service user's credentials from the Aiven Console. Create a dedicated service user for Data Prepper rather than using the default admin account.
A minimal configuration has three pipelines. The entry pipeline uses Data Prepper's otlp source, which accepts OTLP over gRPC or HTTP on port 21893, and passes every span to two more pipelines, one that writes the spans and one that builds the service map:
Loading code...
The index_type setting is what connects this pipeline to Trace Analytics. With trace-analytics-raw, Data Prepper writes spans behind the otel-v1-apm-span alias with the mappings Trace Analytics expects, and trace-analytics-service-map does the same for the service map. On the source, unframed_requests and traces_path let the collector's standard OTLP/HTTP exporter send to /v1/traces, and traces_output_format: opensearch writes spans in the format the Trace Analytics indexes use. The route sends only traces down these pipelines, because the same source also accepts logs and metrics. The certificate and key secure Data Prepper's own endpoint, so issue them from your own certificate authority. The connection to Aiven for OpenSearch needs no certificate settings, because the service uses a publicly trusted certificate.
Data Prepper keeps state in memory. The otel_traces processor holds root spans until a trace completes, and service_map evaluates relationships over a window of 180 seconds by default. To run more than one instance, enable Data Prepper's peer forwarder so that every span of a trace reaches the same instance.
The OpenTelemetry Collector also has an OpenSearch exporter, and in its otel-v1 mapping mode it writes spans in the format Trace Analytics reads. It doesn't build the service map, and it is still at alpha stability, so choose Data Prepper when you want the service map as well as trace search.
Investigating a request in Trace Analytics
Trace Analytics is part of the Observability plugin in OpenSearch Dashboards 3.x, and in Aiven for OpenSearch 3.6 and later it appears as Traces under Observability in the Dashboards menu. An investigation usually moves through four views.
The services view shows which service changed. It lists each service with its latency, error rate and request rate, so you can spot the one that regressed after a deployment.
The service map view shows whether that service is the cause. It draws the calls between services and colors each one by latency, error rate or throughput. A slow service whose downstream dependencies are also slow is usually waiting on them, not causing the delay.
The traces view narrows the problem to specific requests. It groups requests into trace groups, typically an HTTP method and route, with average latency and error rate for each group, and you can filter down to individual traces by service, latency or status.
The trace details view shows where the time went. It displays a single trace as a Gantt chart of its spans, with the attributes of each span, so the database call or downstream request that took most of the time stands out.
From a trace or a single span, View associated logs opens the log records with the same trace ID or span ID. This works only when your logs carry those IDs, and OpenTelemetry's logging instrumentation for most languages can add them to every log record written while a span is active. Since OpenSearch 3.1, you can point Trace Analytics at an existing log index and map its timestamp, service name, trace ID and span ID fields. The log pipeline from the previous post then works as it is, once its log records include trace context.
Buffering traces with Kafka
The buffer-and-route pattern from the previous post applies to traces, with the collector in the role the log forwarder played for logs. The collector's Kafka exporter publishes spans to a topic, otlp_spans by default, encoded as OTLP Protobuf. A second group of collectors reads the topic with the Kafka receiver and forwards spans to Data Prepper. Kafka absorbs the surge of spans during an incident and keeps them for the topic's retention period. To reprocess them after a Data Prepper pipeline change, start the collectors with a new group_id and initial_offset: earliest. Replayed spans overwrite their originals in the current span index, because Data Prepper uses the trace and span IDs as document IDs.
Set partition_traces_by_id on the Kafka exporter so that all spans of a trace land on the same partition. Tail sampling and Data Prepper's trace processing both need the complete trace in one place, and partitioning by trace ID keeps each trace together through the buffer.
Controlling trace volume in OpenSearch
Most traces are never opened, but every one of them costs storage. Every request creates several spans, and OpenSearch stores each span as its own indexed document, so storage grows with request volume rather than with how often people open Trace Analytics.
Tail sampling is the main control. The collector's tail sampling processor waits until a trace is complete, 30 seconds by default, and then decides whether to keep it. A typical policy keeps every trace with an error or a latency above a threshold, plus a small percentage of the rest. Sampling changes what Trace Analytics measures, because it calculates latency, error rate and request rate from the spans it stores. A policy that keeps every error trace but only a fraction of the rest makes error rates look higher than they are, so read those numbers as a view of the sample rather than of all traffic. The processor needs every span of a trace to reach the same collector, which the Kafka partitioning above provides. Without Kafka, put the collector's load-balancing exporter, routing by trace ID, in front of the collectors that sample.
Retention is the second control. Aiven for OpenSearch includes Index State Management, so a policy can roll over the span index by size or age and delete old indexes after a set number of days. A later post in this series covers hot/warm data tiering, sizing and archiving to object storage.
Implementing a trace pipeline: configure, not build
Tracing on OpenSearch takes four pieces you configure rather than build, and because they connect through OTLP, an open standard, you can choose and combine collection tools to fit your use case without changing your code. OpenTelemetry SDKs instrument your code without tying it to a backend, the OpenTelemetry Collector gathers and samples spans, Data Prepper writes them to the indexes that Trace Analytics reads, and Aiven for OpenSearch runs the cluster and OpenSearch Dashboards for you. Because the collector sits between your applications and OpenSearch, putting Kafka in front later is a pipeline change, not an application change.
Next in the series: Security and audit logs. Start from the first post: Observability is a data problem
Try it: Create an Aiven for OpenSearch service on the free plan. Clone the Data Prepper repository and open the Jaeger HotROD example in examples/jaeger-hotrod, which starts a sample application, an OpenTelemetry Collector and Data Prepper with Docker Compose. Point the OpenSearch sink in its Data Prepper pipeline at your service URI and credentials, click through the sample application to generate requests, and open Observability > Traces in OpenSearch Dashboards to see the services, service map and traces. Start free on Aiven
